How Data Ops Makes Unified Namespace Work for Industrial Teams
I have spent the better part of a decade working alongside plant engineers, IT architects, and data scientists in manufacturing environments. One thing I have learned is that the hardest part of digital transformation is rarely the hardware. It is almost always the data. You can install the best sensors, deploy the fastest networks, and buy the most expensive analytics platform, but if your data is scattered across silos, formatted differently by every vendor, and stale by the time it reaches a dashboard, you are essentially flying blind.
The concept of a Unified Namespace has gained traction in Industrie 4.0 circles because it promises a single semantic layer where every piece of information, from a temperature reading on a conveyor belt to a quality metric in an ERP system, can be discovered and understood without translation. But a namespace alone is not enough. You need a disciplined approach to how that namespace is populated, maintained, and consumed. That is where data ops comes in.
Data ops is the practice of treating data operations with the same rigor that DevOps applies to software delivery. It is about building repeatable pipelines, enforcing governance, and monitoring the health of your data flows so that the Unified Namespace remains a source of truth rather than another silo. When I first encountered this idea in a smart manufacturing context, it struck me as obvious but rarely executed. Teams invest heavily in streaming platforms and digital twin models, then wonder why the twin diverges from reality within hours. The culprit is almost always a failure in operational discipline around data.
The Role of Real-Time Data in a Unified Namespace
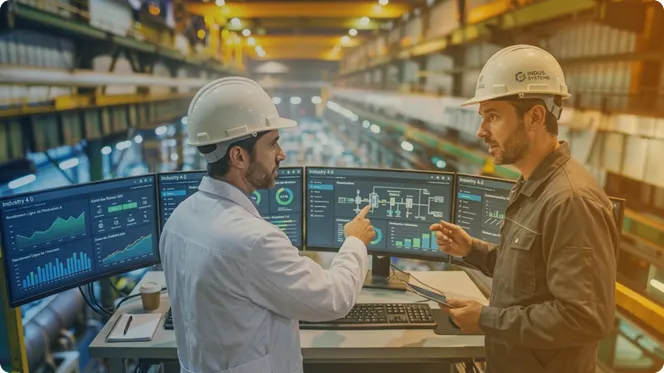
Real-time data is the lifeblood of any industrial IoT deployment. Without it, a digital twin is just a static model. But real-time data introduces a set of challenges that batch processing does not. Latency, ordering, and missing values become critical. In one project I advised, a chemical plant was using OPC UA to pull temperature and pressure readings from dozens of reactors into a central data fabric. The initial setup worked well, but as more equipment came online, the OPC UA servers would occasionally drop packets under load. The stream processing layer, built on Kafka and a time-series database, would ingest the data but with gaps. The digital twin would show normal conditions while the actual reactor was approaching a threshold.
The fix was not a better Kafka cluster or a faster database. It was a set of data ops practices: automated checks that flagged missing readings within seconds, a data catalog that recorded the expected frequency of each signal, and a feedback loop that alerted the control room when the pipeline fell behind. The Unified Namespace remained coherent because the operations around it were explicit and monitored.
Governance Without Bureaucracy
Data governance often gets a bad reputation in industrial settings. Engineers see it as a set of rules written by people who have never touched a PLC. But governance done right is not about slowing things down. It is about knowing who is responsible for each piece of data and what it means. In a data mesh architecture, where domain teams own their data products, governance becomes a shared responsibility. Each team publishes its data with a schema, a description, and a service-level agreement. The Unified Namespace becomes a registry of those contracts.
Data ops provides the tooling for that registry. When a team updates its asset administration shell for a new piece of equipment, the data catalog is updated automatically. When a downstream consumer queries the namespace, they see not just the current value but the lineage, the freshness, and the owner. This transparency reduces the friction that kills cross-team collaboration. I have seen this work in practice at an automotive supplier that used MQTT to stream vibration data from assembly robots. Every robot had an asset administration shell that defined its signals. The data ops layer validated each incoming message against the shell and rejected anything that did not match. The result was a self-healing pipeline that caught misconfigurations before they corrupted the digital twin.
Edge Computing and the Need for Local Discipline
Not every decision can wait for a round trip to the cloud. Edge computing brings processing close to the machinery, which reduces latency and preserves bandwidth. But edge nodes are also the most likely to run without constant human oversight. If an edge gateway loses connectivity or runs out of storage, the data ops layer needs to detect that and either queue the data locally or fall back to a simpler model.
I worked with a food processing company that deployed edge devices to monitor temperature in refrigeration units. Each device ran a stream processing agent that published to a local Kafka broker. The central Unified Namespace aggregated these streams, but the edge nodes operated independently for hours at a time. The data ops framework included a heartbeat mechanism. Every edge node sent a status message every thirty seconds. If the central system did not hear from a node, it marked that node as stale and stopped using its data in the plant-wide digital twin. When connectivity returned, the node replayed its backlog, and the namespace recalculated. This design required no manual intervention. It was a direct result of thinking about operations as a first-class concern.
Practical Steps for Getting Started
If you are leading a digital transformation effort and want to adopt data ops, here are a few concrete actions I have seen work across different industrial sites.
- Start with a small set of high-value data pipelines. Pick three or four signals that feed a critical digital twin or a real-time dashboard. Document their sources, schemas, and latency requirements in a data catalog. This becomes your pilot for the Unified Namespace.
- Automate validation at the ingestion point. Use OPC UA or MQTT metadata to check that each message conforms to the expected shape. Reject or quarantine anything that deviates. This catches integration errors early.
- Instrument every pipeline with health metrics. Track throughput, latency, error rate, and staleness. Publish those metrics into the namespace so that operators can see the health of the data ops layer itself.
- Define ownership explicitly. For each data product, name a team or person responsible. In a data mesh, ownership is decentralized, but it must be recorded. The asset administration shell is a natural place to hold that information.
- Run regular drills. Simulate a network partition or a sensor failure and watch how the system reacts. Use what you learn to improve the automated responses. This builds confidence in the operational discipline.
The Connection to Data Sovereignty
Data sovereignty is becoming a major concern, especially in European manufacturing where regulations like the GDPR impose strict rules on data movement. A Unified Namespace can help by providing a single point of control. If you know exactly where each piece of data lives, who owns it, and what it contains, you can enforce policies about where it can be stored or processed. Data ops makes that enforcement operational. When a data pipeline tries to replicate a sensitive signal to a region where it should not go, the governance layer blocks it and logs the event. This is not a theoretical benefit. I have seen it implemented in a factory that used a data fabric to separate process data from personal data, with the namespace acting as the policy decision point.
One of the more subtle lessons I have learned is that data ops is not a one-time project. It is a continuous practice. The industrial environment changes. New machines are added, old protocols are retired, business questions evolve. The data operations must adapt without breaking existing consumers. That is why a Unified Namespace built on flexible standards like OPC UA and MQTT is a good foundation. But the namespace needs a caretaker, and that caretaker is a set of automated processes, not a person.
In my experience, the teams that succeed with smart manufacturing are the ones that treat their data infrastructure as a living system. They invest in monitoring, they enforce naming conventions, and they review their pipelines regularly. They do not wait for a crisis to discover that a data source has been silent for a week. They have built the reflexes of data ops into their daily work.
The result is that their digital twins stay accurate, their real-time dashboards stay current, and their industrial IoT investments actually pay off. The Unified Namespace becomes a trusted resource rather than a theoretical diagram. And that trust is what allows engineers to move fast, experiment, and innovate without worrying about the data beneath them.